
Local first
Core functions can run on hardware you control at home or inside an organization.
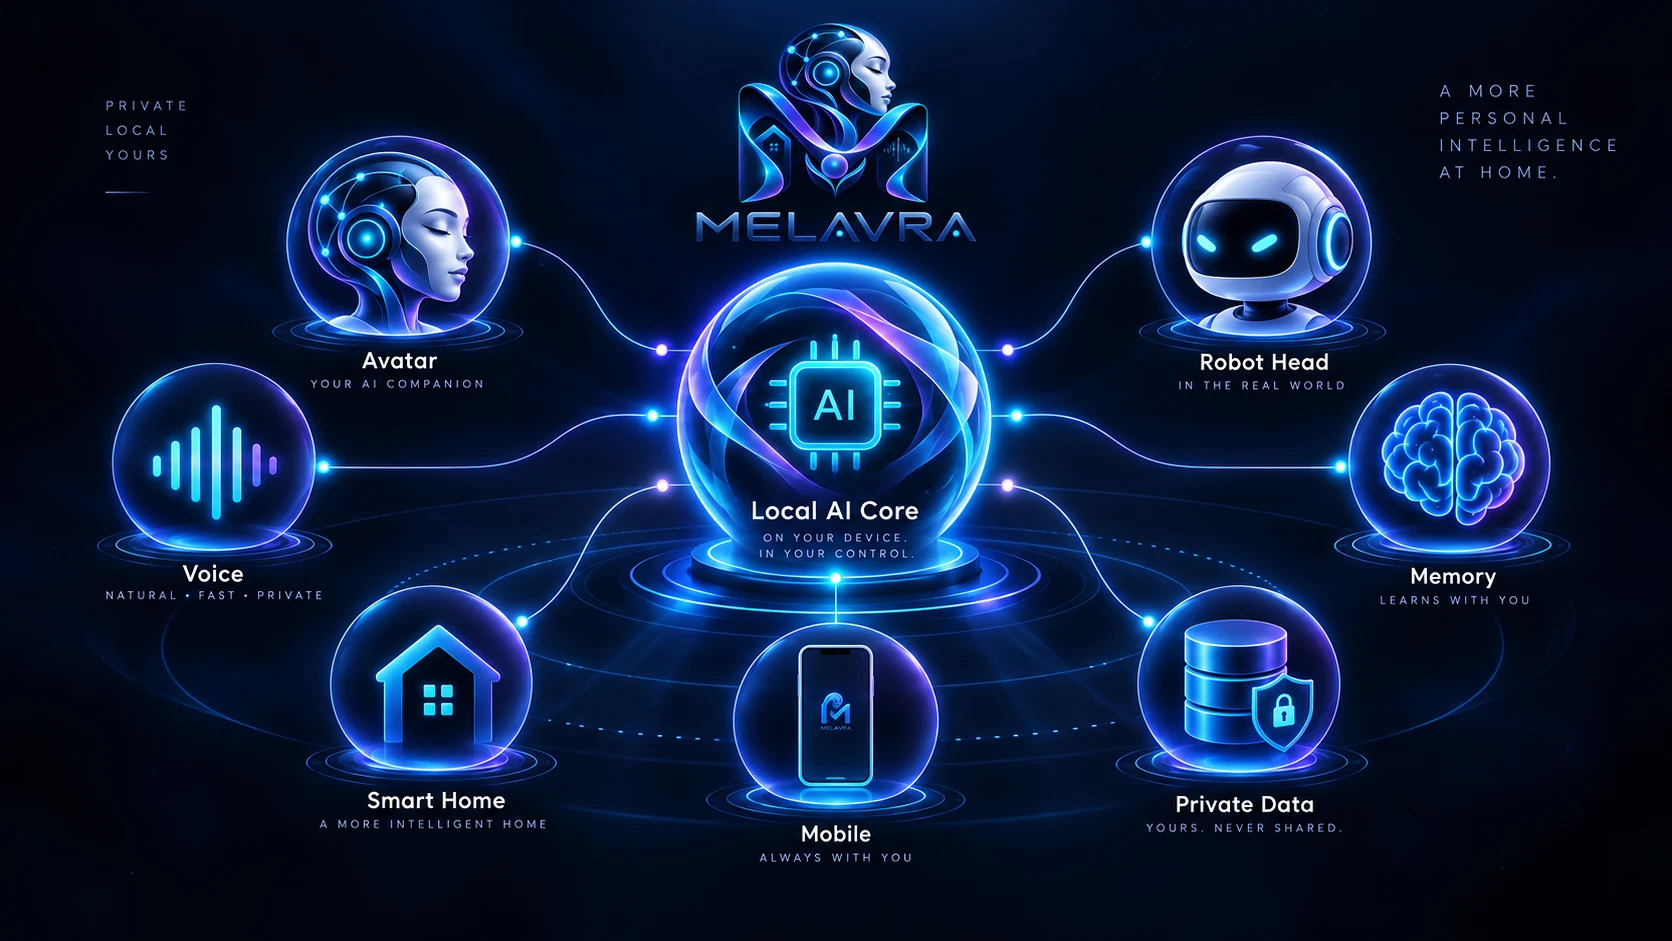
MELAVRA connects a local AI core, voice, long-term memory, digital avatar, robot head and smart home — under your control.
The same persona can appear on a PC, smartphone, display, avatar and physical robot head. Voice, context, memories and behavior remain parts of one coherent local environment.
Core functions can run on hardware you control at home or inside an organization.
MELAVRA is designed around the owner, their language, routines, roles and preferences.
The intelligence can become present through voice, avatar, robot head and future physical devices.
The AI core is not tied to one screen. MELAVRA is designed as a platform that connects multiple devices and forms of expression to one persona.
Status labels deliberately separate what works today, what runs as a prototype and what is still being developed.
Local models and runtime on hardware you control.
Local speech recognition, dialogue and speech synthesis.
Facial expression, gaze, blinking, micro-expression and behavioral states.
Physical presence with eyes, eyelids, mouth, head movement and audio.
Long-term context, preferences and personal working history.
LAN client for dialogue, avatar streaming and local communication.
One persona as a natural control and context layer for the home.
Cameras and sensors as additional local context.
Local language models, voice, persona and supporting services can run on your own hardware. Online services remain optional extensions instead of a requirement.
The goal is not to require private conversations and personal memories to be sent to external cloud services. Local processing is the foundation; external services are added deliberately when they provide a clear benefit.
MELAVRA also covers workflows for preparing speech and training data, evaluation, model testing and future adaptation to concrete tasks.
MELAVRA is developed as a continuous R&D system. Current capabilities and future goals are therefore shown separately.
Microphone → local speech recognition → local LLM → local speech synthesis → playback on the target device.
Expression, motion and audiovisual output are being combined into a physical presence.
Continuous context, owner preferences, roles, rules and retrievable knowledge traces.
Future owner recognition, authorized speakers and context-aware responses.
Control devices, sensors, schedules and local services through the same persona.
The English long form remains part of the brand. Each component is explained in the selected language.
Messages are stored directly on this server and can be reviewed in the administration panel.